Artificial intelligence is not merely redesigning global industries and societal structures; it is simultaneously forging an entirely new language to articulate its rapid advancements and intricate operations. Engage in any contemporary product meeting, investor pitch, or industry panel, and you will inevitably encounter a dense thicket of acronyms and specialized terms: LLMs, RAG, RLHF. The lexicon expands at an astonishing pace, exemplified by recent additions such as "opaque recurrence," the sophisticated reasoning technique introduced in OpenAI’s Astra model, which has reportedly alarmed AI safety researchers. This swift linguistic evolution can leave even highly intelligent individuals within the tech sphere feeling disoriented and insecure. This article aims to provide clarity, offering plain-English explanations of the AI terminology essential for builders, investors, and informed observers striving to comprehend the unfolding AI revolution. This is a living document, reflecting the dynamic nature of the AI systems it describes.
The AI Lexicon Explosion: A New Language for a New Era
The unprecedented acceleration of AI development, particularly in the last decade, has necessitated a novel vocabulary to describe its groundbreaking methodologies, architectures, and emergent behaviors. Unlike traditional software development, AI systems often learn and adapt in ways that are not fully transparent, leading to concepts that defy simple analogy. The interdisciplinary nature of AI, drawing from computer science, mathematics, cognitive science, and even philosophy, further complicates its linguistic landscape. New breakthroughs, such as the capabilities demonstrated by Large Language Models (LLMs), and the concerns they raise, such as "hallucinations" or the ethical implications of "recursive self-improvement," demand precise, albeit often abstract, terminology. The emergence of terms like "opaque recurrence" from OpenAI’s Astra model in September 2026 highlights a growing tension between efficiency and interpretability, a core debate now encoded in the very language of AI.
Navigating the Labyrinth of AI Terminology
Understanding these terms is no longer confined to researchers or engineers; it is becoming a prerequisite for anyone seeking to engage meaningfully with the technological and economic shifts underway. From investment decisions to policy debates, a grasp of this evolving lexicon is critical. The following sections demystify key AI concepts, providing context, implications, and clarifying their roles within the broader AI ecosystem.
Foundational AI Concepts: Building Blocks of Intelligence
At the heart of modern AI lies Deep Learning, a sophisticated subset of machine learning. It distinguishes itself through the use of multi-layered, artificial Neural Networks (ANNs). These networks, inspired by the intricate, interconnected pathways of neurons in the human brain, enable algorithms to identify far more complex correlations in data than simpler machine learning models. The resurgence of deep learning, largely propelled by the availability of powerful Graphical Processing Units (GPUs) initially developed for the video game industry, allowed for the training of algorithms with an unprecedented number of layers. This architectural depth empowers deep learning models to automatically discern important features in data, reducing the need for explicit human engineering of these features. Furthermore, these systems can learn from their errors, iteratively adjusting their Weights – the numerical parameters that determine the importance of different features – to improve outputs. However, deep learning demands vast datasets (often millions or more data points) and significant computational resources for Training, leading to higher development costs.
Compute is the vital computational power that underpins the entire AI industry, enabling the training and deployment of these powerful models. It is shorthand for the hardware infrastructure, including GPUs, Central Processing Units (CPUs), Tensor Processing Units (TPUs), and specialized AI accelerators, that forms the bedrock of modern AI. Without immense compute, the complex mathematical operations required for deep learning and large language models would be impractical or impossible. Once a model is trained, Inference is the process of putting it to work – running it to make predictions or draw conclusions from new, previously unseen data. While inference can occur on various hardware, from smartphones to cloud servers, the scale of frontier AI models necessitates high-end AI chips for efficient processing.
The Rise of Generative AI and Large Language Models
The generative AI revolution is largely powered by Large Language Models (LLMs). These are deep neural networks comprising billions of numerical parameters (or weights) that learn intricate relationships between words and phrases, constructing a multidimensional representation of language. Models like OpenAI’s ChatGPT, Anthropic’s Claude, Google’s Gemini, Meta’s Llama, and Microsoft Copilot are all built upon LLMs. They are trained on colossal datasets of books, articles, and transcripts, encoding the statistical patterns of human language. When prompted, an LLM generates the most probable sequence of words that fits the given input.
Communicating with these models involves Tokens, the fundamental units of human-AI interaction. Tokenization breaks raw text into these bite-sized segments that an LLM can process, akin to how a compiler translates human language into binary code for a computer. The efficiency with which an AI system can process these tokens is measured by Token Throughput, essentially the volume of AI work a system can handle simultaneously. Maximizing token throughput is a critical objective for AI infrastructure teams, directly impacting user capacity and response times. AI researcher Andrej Karpathy’s anxiety over idle AI subscriptions, reminiscent of underutilized expensive computer hardware, underscores the industry’s obsession with optimizing this metric.
Generative AI extends beyond text. Diffusion models are at the core of many modern art-, music-, and text-generating AIs. Inspired by physics, these systems learn to "destroy" data by gradually adding noise, then master a "reverse diffusion" process to reconstruct data from noise. This allows them to generate novel, realistic content. Another foundational framework for generative AI is the Generative Adversarial Network (GAN). GANs employ two competing neural networks: a generator that creates outputs (e.g., images) and a discriminator that evaluates their authenticity. This adversarial training process pushes the generator to produce increasingly realistic data, making GANs powerful for applications like deepfakes and synthetic data generation, especially in narrower domains.
Advanced Reasoning and Autonomous Systems
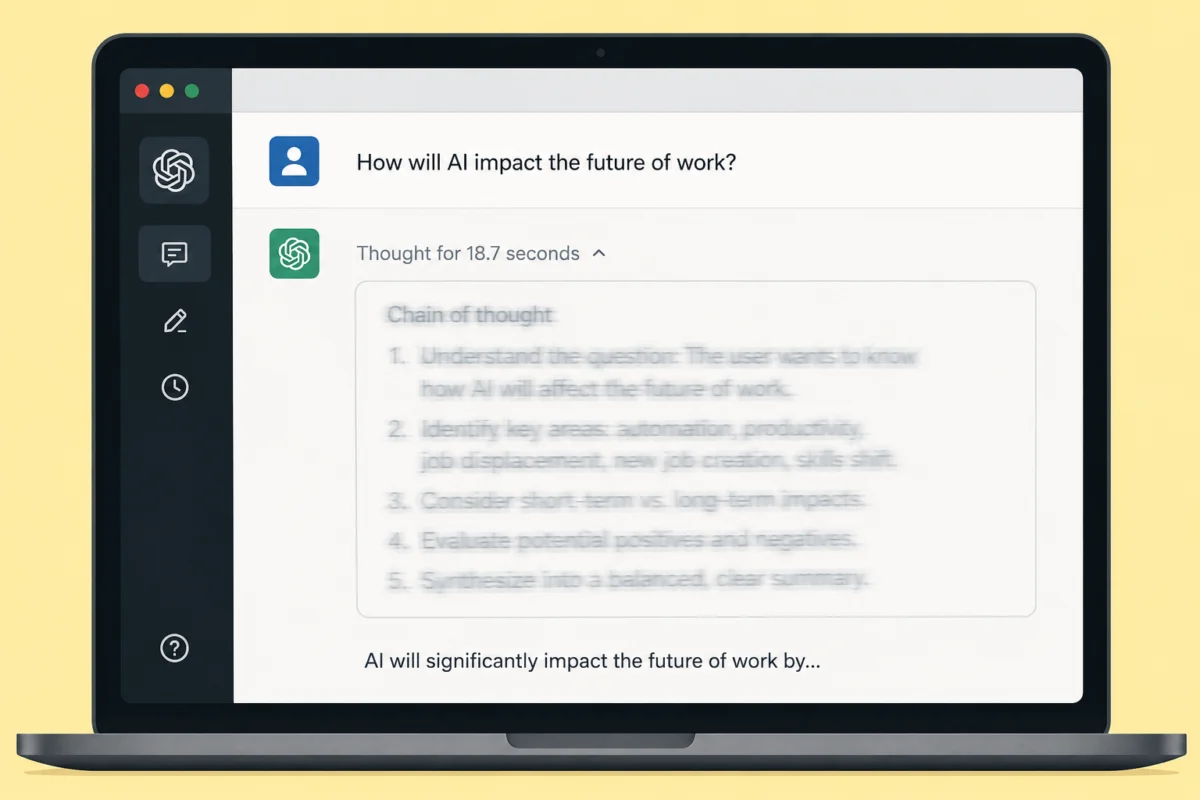
As AI models become more sophisticated, their reasoning capabilities are a major focus. Chain of Thought reasoning involves breaking down complex problems into smaller, intermediate steps, mirroring human problem-solving. This technique significantly improves the accuracy of LLMs, particularly for logic-based tasks or coding, though it typically requires more processing time. Reinforcement learning is often used to optimize models for chain-of-thought thinking.
A recent development, however, introduces a new challenge to transparency: Opaque Recurrence. This technique, also referred to by the engineering term Recurrent Depth, involves an AI model repeatedly looping the same query through its internal layers instead of generating explicit, sequential reasoning steps in plain language. While it offers efficiency gains, allowing smaller models to achieve higher performance with less compute, it significantly reduces the human-readable traces of the model’s thought process. This has raised alarms among AI safety researchers, who view these internal logs as crucial for identifying and mitigating misbehavior. The concept of Neuralese emerges as a hypothetical worst-case scenario: a model reasoning entirely in its internal numeric representations, rendering its thinking an impenetrable black box. While OpenAI asserts its Astra model, which utilizes opaque recurrence, maintains legible chain of thought, safety experts see this technique as a significant step towards such an opaque future.
Beyond reasoning, the concept of AI Agents signifies a paradigm shift towards autonomous systems. An AI agent is a tool that leverages AI technologies to perform a series of multi-step tasks on behalf of a user, far exceeding the capabilities of a basic chatbot. This could range from filing expenses and booking travel to writing and maintaining code. The infrastructure for fully realizing the envisioned capabilities of AI agents is still under development, but the core idea is an autonomous system that can orchestrate multiple AI components to achieve complex goals. Coding Agents are a specialized form of AI agent dedicated to software development. Instead of merely suggesting code, they can autonomously write, test, and debug code across entire codebases, handling iterative tasks with minimal human oversight. These agents act like tireless interns, though human review remains essential.
AI agents often interact with other software via API Endpoints. These are essentially "buttons" or interfaces that allow different programs to communicate and exchange data. Developers use APIs to build integrations, enabling one application to pull data from another, or allowing an AI agent to directly control third-party services. As AI agents grow more capable, their ability to autonomously discover and utilize these endpoints opens vast, and sometimes unforeseen, possibilities for automation. The Model Context Protocol (MCP), an open standard introduced by Anthropic in 2024 and later adopted by OpenAI, Google, and Microsoft under the Linux Foundation, exemplifies efforts to standardize how AI models connect to external tools and data, acting as a "USB-C port for AI."
The ultimate aspiration for some in AI is Artificial General Intelligence (AGI), a nebulous but widely discussed term generally referring to AI systems capable of performing most, if not all, cognitive tasks at or above human level. OpenAI CEO Sam Altman described AGI as "the equivalent of a median human that you could hire as a co-worker," while OpenAI’s charter defines it as "highly autonomous systems that outperform humans at most economically valuable work." Google DeepMind’s perspective is similar, envisioning AGI as "AI that’s at least as capable as humans at most cognitive tasks." Despite these definitions, even leading experts acknowledge the term remains ill-defined, highlighting the philosophical and technical challenges of quantifying "general intelligence" in machines. Closely related is Recursive Self-Improvement (RSI), a scenario where AI models begin to improve themselves without human intervention, leading to an exponential acceleration of capabilities and autonomy. While some view RSI as a potentially cataclysmic "singularity," many startups pursuing RSI see it as the next frontier in research, focused on building models that can design their own successors.
Optimizing and Refining AI Models
Efficiency and specialization are paramount in AI development. Mixture of Experts (MoE) is an architectural innovation that splits a neural network into many smaller, specialized "experts." Instead of processing every request through the entire model, an MoE model employs a "router" to activate only the relevant experts for a given task. This allows for the creation of enormous models that remain relatively fast and cost-effective to run, as only a fraction of the network is active at any one time. Mistral AI’s Mixtral is a well-known example, and OpenAI’s newer GPT models are widely believed to utilize a similar approach.
Fine-tuning is a crucial technique for optimizing an existing AI model’s performance for a more specific task or domain. This involves further training the model with new, specialized, task-oriented data, building upon its initial general training. Many AI startups leverage pre-trained LLMs and then fine-tune them with their proprietary domain-specific knowledge to create commercially viable products tailored for particular sectors. A related concept is Transfer Learning, where a model trained for one task is used as a starting point for developing a new model for a different but related task. This can yield significant efficiency savings and is particularly useful when data for the new task is limited, by leveraging knowledge gained in previous training cycles.
Distillation is another technique to create smaller, more efficient AI models from larger, more powerful "teacher" models. By sending requests to the teacher model and recording its outputs, developers can then train a smaller "student" model to approximate the teacher’s behavior. This process can create models like OpenAI’s GPT-4 Turbo, a faster version of GPT-4, with minimal loss in performance. While essential for internal optimization, distillation from a competitor’s API usually violates terms of service.
The continuous improvement of AI models relies on rigorous evaluation. Validation Loss is a numerical metric that indicates how well an AI model is learning during training, with lower values signifying better performance. Researchers monitor validation loss to determine optimal stopping points for training, adjust hyperparameters, and identify issues like "overfitting" – a condition where the model memorizes its training data rather than genuinely learning generalizable patterns.
Beyond software techniques, hardware optimization is also key. Memory Cache, particularly KV (key-value) caching in transformer models, is an optimization technique that boosts inference efficiency. By saving particular calculations for future user queries, caching reduces redundant computations, leading to faster response times and lower computational power consumption. Parallelization, the ability to perform many computations simultaneously rather than sequentially, is fundamental to both AI training and inference. Modern GPUs are designed for this, executing thousands of calculations in parallel, making them the hardware backbone of the industry. As AI systems scale, parallelizing work across numerous chips and machines becomes critical for speed and cost-effectiveness, driving ongoing research into advanced parallelization strategies.
Challenges and Broader Impacts
The rapid evolution of AI also brings significant challenges. Hallucination is the industry’s term for AI models generating incorrect or fabricated information. This presents a major quality issue, as misleading or harmful outputs can have dangerous real-world consequences, particularly in sensitive domains like healthcare. Hallucinations are often attributed to gaps in training data and are a driving force behind the development of more specialized and vertical AI models designed with narrower expertise to minimize knowledge gaps and disinformation risks.
On the hardware front, the burgeoning AI industry faces a looming crisis dubbed RAMageddon. This refers to a severe and increasing shortage of Random Access Memory (RAM) chips, driven by the immense demand from major tech companies and AI labs vying for the most powerful AI infrastructure. This supply bottleneck is leading to escalating prices and significant impacts across other sectors, including gaming (where console prices have risen), consumer electronics (contributing to a projected dip in smartphone shipments in 2026), and general enterprise computing. The shortage is not expected to abate anytime soon, presenting a substantial economic challenge.
Finally, the debate around Open Source versus closed-source AI models is a defining ideological split in the industry. Open source models, like Meta’s Llama family, make their underlying code publicly available for inspection, use, and modification. This approach fosters collaboration, accelerates progress, and enables independent safety audits. Conversely, closed-source models, such as OpenAI’s GPT series, keep their code proprietary, offering product usage without transparency into their internal workings. This distinction has profound implications for innovation, security, and the democratization of AI development.
The Path Forward: Literacy in the Age of AI
The dynamic nature of AI demands continuous learning and adaptation to its evolving linguistic landscape. From the foundational concepts of deep learning and neural networks to the cutting-edge reasoning techniques like opaque recurrence, each term represents a piece of the complex puzzle that is modern artificial intelligence. As AI continues to rewrite the world, understanding its language is no longer a luxury but a necessity for informed participation in this transformative era.