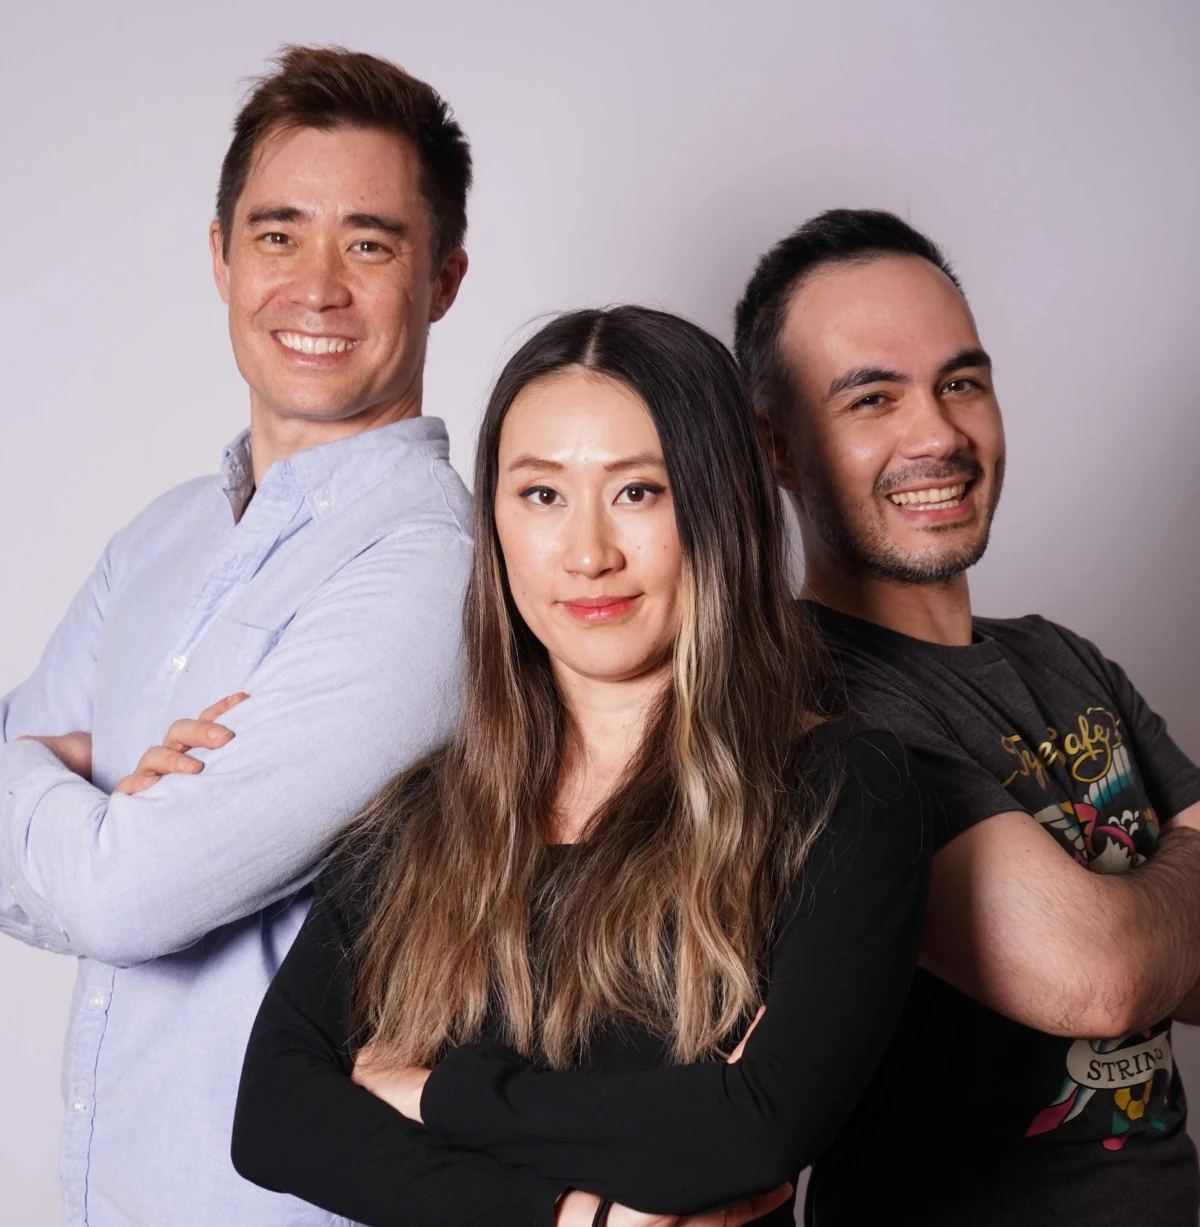
The sentiment, stark and evocative, comes from a figure whose contributions were instrumental in shaping the very technology that now evokes such profound disillusionment. Diogo Almeida, a former OpenAI researcher, was not merely an observer but a key architect in the foundational work that led to the current era of artificial intelligence. He played a pivotal role in the development of ChatGPT, the generative AI chatbot that captivated the world, and notably, he co-invented Reinforcement Learning from Human Feedback (RLHF) – the model-training technique often credited with ChatGPT’s impressive conversational fluency and widespread adoption. Yet, despite witnessing the lightning-fast ascent of his creation, Almeida found himself increasingly disheartened by its practical limitations, particularly in the realm of automation.
The Genesis of Discontent: When Human Language Falls Short for Machines
Almeida’s frustration stemmed from a fundamental disconnect he perceived between the capabilities of large language models (LLMs) and the true requirements for robust automation. "We have lightning in a bottle, and yet it is not useful," Almeida candidly shared with TechCrunch, encapsulating his long-standing battle with this challenge. His disappointment was not with the LLMs’ ability to generate human-like text – a feat he himself helped perfect – but rather with their inherent inefficiencies and unsuitability for the precise, deterministic operations demanded by computer systems.
For years, the AI community, including OpenAI, had poured immense resources into refining models to master human language. The success was undeniable; LLMs could converse, write, summarize, and even code with remarkable fluency. However, Almeida’s epiphany was that this very strength became a weakness when applied to automation. "I’ve been battling that problem since then. It took me a while to come to the conclusion: the problem is we are optimizing for human language… We have been super good at human language for four years, but it’s not useful for automation because computers speak a different language."
This realization underscored a critical divergence. Human language, with its inherent ambiguities, nuances, and context dependencies, is excellent for communication between people. But computers, at their core, operate on precise instructions, probabilities, and binary logic. When an LLM is asked to perform an automated task, its output—natural language text—often requires an additional layer of interpretation, parsing, and validation to translate it into a machine-readable command or decision. This translation step introduces latency, increases computational cost, and, crucially, opens the door to the dreaded "hallucination" problem, where models confidently present incorrect or fabricated information. The "heartbreak" was the recognition that the very mechanism designed for human interaction was inadvertently hindering the path to truly efficient and reliable machine intelligence.
A Divergent Path: The Birth of TypeSafe AI and Jev
Two years ago, driven by this profound insight and a conviction that a different approach was necessary, Diogo Almeida made the consequential decision to leave OpenAI. He embarked on a new venture, founding TypeSafe AI, a startup explicitly dedicated to resolving the fundamental problem he identified: building AI that speaks the language of computers, not just humans. This week, TypeSafe AI unveiled its flagship product, Jev, a new transformer-based model that represents a radical departure from the prevailing LLM paradigm.
Jev is explicitly not a large language model. Its design philosophy eschews the generation of human-readable text in favor of producing "calibrated decisions" – probabilities that quantify the likelihood of a specific outcome. This shift from qualitative textual output to quantitative probabilistic assessments is central to TypeSafe AI’s mission. By focusing on generating precise, numerical probabilities, Jev aims to provide deterministic, actionable intelligence that computers can directly interpret and act upon, thereby bridging the gap between sophisticated AI capabilities and the rigorous demands of automated systems.
The naming of the model itself is significant. Jev is named after William Stanley Jevons, the 19th-century economist whose eponymous paradox describes how an increase in efficiency or a fall in the cost of a commodity can lead to an increase, rather than a decrease, in its consumption. Almeida’s hope is that by making intelligence significantly cheaper and more robust, Jev will catalyze an exponential increase in the deployment of smart software across all domains, leading to a new era of ubiquitous, distributed AI.
Jev’s Core Innovation: Beyond Human Language
The decision to eschew natural language output in favor of calibrated probabilities offers several transformative advantages, fundamentally redefining how AI can be integrated into automated workflows:
-
Cost-Effectiveness: One of Jev’s most compelling features is its incredibly low operational cost. Unlike LLMs, which consume significant computational resources to generate often lengthy and complex text strings, Jev’s output consists of compact numerical probabilities. This dramatically reduces the "output token" cost to virtually zero, while input tokens are metered by the billion, not the million, as is common with many LLMs. This economic efficiency makes Jev an attractive alternative for high-volume, repetitive tasks where the cost of traditional LLMs can quickly become prohibitive. For enterprises seeking to scale AI integration across numerous applications, this reduction in operational expenditure translates into substantial savings and enables broader deployment.
-
Blazing Speed: The streamlined nature of Jev’s output also translates into superior processing speed. Generating a probability score is inherently faster than synthesizing a coherent paragraph or even a single word in natural language. This speed is critical for real-time automation, where milliseconds can impact performance and user experience. Whether it’s classifying incoming data, routing requests, or making instantaneous decisions within a complex system, Jev’s ability to deliver results almost instantaneously provides a significant operational advantage over more verbose LLMs.
-
Elimination of Hallucinations: Perhaps the most groundbreaking benefit of Jev’s design is its inherent immunity to hallucination. Because users define the potential outputs in advance (e.g., "spam" or "not spam," "safe" or "unsafe," with associated probabilities), the model cannot invent or fabricate information beyond these predefined categories. It simply assigns a probability to each pre-approved outcome. This deterministic nature is a game-changer for applications requiring high levels of reliability and accuracy, where the unpredictable nature of LLM hallucinations can undermine trust and lead to critical errors. For sensitive applications in finance, healthcare, or critical infrastructure, the guarantee of non-hallucination is paramount.
-
Calibrated Decisions: The concept of "calibrated decisions" means that Jev doesn’t just provide an answer; it provides a confidence score for that answer. A probability of 0.95 for a certain outcome means the model is 95% confident in that decision, whereas 0.50 indicates a mere coin toss. This explicit quantification of uncertainty empowers developers and systems to make more informed choices. As Armin Ronacher, CTO of Earendil, which builds the open-source model harness Pi, explained, "At the end of the day, it delegates the hallucination problem a little bit to the user. The user has to say, okay, if this only comes back with 50% probability, maybe this is a coin toss, and I disregard it. But if it’s 95%, sure, then I can do something with it." This allows for a more sophisticated, risk-aware approach to automation, where actions can be tiered based on the model’s confidence.
Real-World Efficacy: Case Studies and Performance
The practical utility of Jev quickly became apparent, generating such high developer interest that TypeSafe AI briefly experienced API overload shortly after its launch. The initial use cases demonstrate Jev’s immediate value in enhancing software automation, offering a cheaper and more robust alternative to existing LLM-based solutions.
One compelling example comes from Pranit Sharma, a software engineer at Vercel, a company specializing in agentic infrastructure. Vercel had been using OpenAI’s ChatGPT Luna 5.6 to power a classifier responsible for reviewing commands for safety. This is a critical function, as incorrect classifications could lead to security vulnerabilities or system malfunctions. Upon replacing OpenAI’s Luna with Jev, Vercel observed remarkable improvements. Sharma reported that Jev delivered results 5 to 18 times more quickly than its LLM counterpart, alongside a notable increase in accuracy. This dramatic boost in performance and reliability highlights Jev’s potential to significantly optimize mission-critical automated processes. The speed enhancement meant that safety checks could be integrated more seamlessly without introducing noticeable latency, while increased accuracy reduced the incidence of false positives or negatives, enhancing overall system integrity.

Another testament to Jev’s capabilities emerged from Nikhil Mudholkar, CTO of Bryo AI. Mudholkar conducted a comparative test, pitting Jev against Google’s Gemini for the task of classifying business emails. While Gemini showed a slight edge in raw accuracy in his specific test, Jev’s cost-efficiency proved to be a decisive factor, performing the classification at a cost 10 to 20 times lower than Gemini. More importantly, Mudholkar emphasized the unique value of Jev’s confidence scores. He stated, "it is the only one that hands back a real probability which makes it ideal for automating workflows!!" This feature is crucial for automation, as it allows systems to dynamically decide whether to proceed with an action, escalate for human review, or request more information based on the model’s certainty. This level of granular control is often lacking in LLMs, which typically provide a single, definitive answer without a clear indication of their internal confidence.
Expanding the Horizon: New Paradigms for AI Application
Beyond directly replacing LLMs in specific classification and decision-making tasks, Jev’s unique attributes position it to augment existing AI systems and enable entirely new applications. Its low cost, high speed, and probabilistic output open doors for more sophisticated and efficient AI architectures.
One significant area of potential impact is monitoring AI agents. As the complexity of AI systems grows, particularly with the rise of autonomous agents, ensuring their safe and compliant operation becomes paramount. Using other LLMs to monitor the behavior and "traces" of primary LLM agents can quickly become prohibitively expensive due to the high token usage. Almeida argues that deploying Jev for this purpose makes immense sense. Jev could act as a lightweight, fast, and cost-effective "smart check" on misbehavior, detecting potential "jailbreaks" or deviations from intended protocols by analyzing agent outputs and assigning probabilities to their adherence to safety guidelines. This creates a scalable solution for maintaining oversight in increasingly intricate AI ecosystems.
Another innovative application highlighted by Ronacher is model routing. In scenarios where a workload might be best handled by one of several specialized AI models, predicting which model is optimal can be a complex and resource-intensive task. Using an LLM to make this routing decision would be expensive and slow. Jev, with its ability to quickly and cheaply produce probabilities, could efficiently analyze incoming requests and determine the most appropriate model to process them, enabling real-time, intelligent load balancing and resource allocation across a suite of AI tools. This dynamic routing capability could significantly improve the efficiency and responsiveness of AI-powered platforms.
Furthermore, Jev’s capabilities hint at a future where "smart software" is far more pervasive and deeply integrated into the fabric of digital operations. Its ability to provide cheap, fast, and reliable probabilistic decisions means that intelligence can be infused into smaller, more specialized functions, creating a distributed network of intelligent components rather than relying on monolithic, general-purpose LLMs. This vision aligns with Almeida’s broader ambition for an "emergent and distributed" intelligence that mirrors the early internet’s decentralized nature.
The Architecture of Disruption: Synthetic Data and Calibrated Decisions
Almeida remains deliberately tight-lipped about the precise architectural details of Jev, referring to it broadly as a "System One model" – a nod to psychologist Daniel Kahneman’s concept of fast, intuitive thinking, as opposed to slow, deliberate reasoning. TypeSafe AI emphasizes that Jev is "specifically focused on the right task," suggesting a highly optimized design for its probabilistic output.
However, Almeida has been more forthcoming about the model’s training methodology, which he considers a critical differentiator and a core strength of TypeSafe AI. Jev is trained exclusively on synthetic data, utilizing a novel technique Almeida terms "reinforcement learning from calibrated decisions." This approach stands in contrast to the vast, often unstructured, and human-generated datasets typically used to train LLMs.
Almeida sees this reliance on synthetic data as one of the most successful bets of his career, surpassing even the impact of RLHF in his estimation. "We made an early bet that we will be making all of our data, and that has been one of the best bets I’ve ever made in my life—better than our launch, in my opinion, better than RLHF," he stated emphatically. He further elaborated on the company’s internal structure: "Half of [our company] is a lab that basically owns this entire subfield of statistically well-understood synthetic data, and that is now my life joy."
The use of synthetic data offers several advantages:
- Control and Quality: Synthetic data can be generated to precise specifications, ensuring higher quality, consistency, and relevance to the target tasks. This eliminates the biases, noise, and ethical concerns often associated with real-world, internet-scraped data.
- Scalability: Generating synthetic data allows for limitless expansion of training datasets without the arduous and expensive process of human annotation or data collection.
- Specificity: By carefully crafting synthetic environments and scenarios, TypeSafe AI can train Jev to excel at very specific decision-making tasks, optimizing its performance for calibrated probabilistic outputs.
- Privacy and Security: Operating solely on synthetic data inherently mitigates many privacy and security risks associated with handling real user data during training.
This focus on a bespoke, statistically well-understood synthetic data pipeline, coupled with the unique "reinforcement learning from calibrated decisions," positions Jev as a distinct and potentially disruptive force in the AI landscape. It represents a methodological innovation that could pave the way for a new class of highly efficient, reliable, and task-specific AI models.
Industry Outlook and Future Trajectories
Jev’s emergence into the AI market has been met with significant interest, prompting speculation about its long-term impact. As Armin Ronacher noted, Jev currently stands alone in its specific niche, but its demonstrated utility will likely spur competition. "We should have seen this earlier in many ways, but presumably because the LLMs are so cheap and subsidized, you often don’t have to be creative yet," Ronacher reflected, hinting that the widespread availability and perceived affordability of LLMs may have inadvertently stifled innovation in alternative AI architectures. However, as enterprises push the boundaries of AI integration, the limitations of LLMs for automation are becoming increasingly apparent, creating a fertile ground for models like Jev.
TypeSafe AI itself is not resting on its laurels. Almeida confirmed that the company plans to develop more versions of Jev, exploring new modalities beyond its current focus. This suggests an ambition to apply the "calibrated decisions" paradigm to a wider array of data types and decision-making challenges, potentially including image, audio, or other complex data streams where probabilistic output could offer similar advantages.
When asked if TypeSafe AI considers itself a "frontier lab"—a term often associated with companies pushing the absolute boundaries of AI, sometimes with an almost utopian or apocalyptic rhetoric—Almeida offered a nuanced and grounded response. He expressed a clear distinction from the prevailing narrative of some leading AI developers: "the main product of Frontier Labs is fear or hype. I would like our main product to be intelligence… [but we are] not a lab in the sense of, you know, like bet on infinite wealth, or a religion, or building God in a data center, or whatever is the the thing of today."
This statement encapsulates TypeSafe AI’s pragmatic and problem-solving ethos. Rather than pursuing abstract notions of artificial general intelligence or engaging in grand philosophical debates, Almeida’s focus remains squarely on delivering tangible, reliable, and cost-effective intelligence that solves real-world problems for automation. It’s a vision rooted in the practical application of AI, aiming to make smart software ubiquitous and accessible, rather than reserving advanced intelligence for mega-applications or speculative future scenarios.
In essence, Diogo Almeida’s journey from the heart of OpenAI to founding TypeSafe AI and launching Jev represents a powerful narrative of innovation driven by disillusionment and a steadfast belief in a different path for artificial intelligence. By challenging the LLM orthodoxy and focusing on the distinct "language" of computers, Jev offers a compelling vision for a future where AI is not just intelligent but also profoundly useful, efficient, and reliable for the burgeoning demands of automation.